
Physical AI & Dexterous Manipulation
사람처럼 손을 쓰는 로봇Robots that use their hands the way people do
무엇을 하나What we do
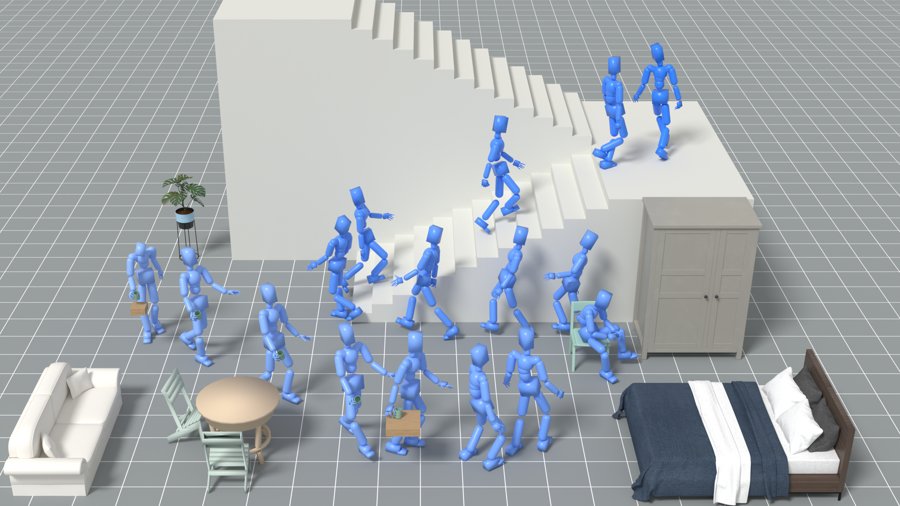
저희가 꿈꾸는 로봇은 사람처럼 움직이며 사람의 노동을 대신하고, 스스로 움직이고 스스로 배워 나아지는 로봇입니다. 그중에서도 사람 손처럼 정교하게 물건을 다루는 능력에 가장 관심이 많습니다. 기준은 사람의 몸입니다. 이 문제를 이미 풀고 있는 유일한 시스템이 사람이기 때문에, 인터넷의 수많은 동영상과 저희가 직접 찍은 사람의 움직임에서 로봇 손과 휴머노이드가 바로 배우게 만듭니다.We dream of robots that move like people and take over the work people do, robots that act on their own and keep improving on their own. What interests us most is dexterity: handling objects with the precision of a human hand. We take the human body as our reference. Humans are the one system that already solves this problem, so robot hands and humanoids learn directly from how people move, whether in the countless videos already on the internet or in the motions we capture in our own lab.
논문Papers 9
- Preprint 2026Co²Skill: Whole-Body Control via Skill Composition for Long-Horizon Human-Environment InteractionPaper Project Page
- Preprint 2026DeVI: Physics-based Dexterous Human-Object Interaction via Synthetic Video ImitationPaper Project Page
- Preprint 2026ZeroDex: Zero-Shot Long-Horizon Dexterous Manipulation via Multi-View 3D-Grounded VLM ReasoningPaper Project Page
- ECCV 2026Text-Guided 6D Object Pose Rearrangement via Closed-Loop VLM AgentsPaper Project Page Code
- CoRL 2026AutoDex: An Automated Real-World System for Dexterous Grasping Data CollectionPaper Project Page Code
- Preprint 2026HRDexDB: A 4D Dexterous Grasping Dataset Across Human and Multiple Robot EmbodimentsPaper Project Page
- NeurIPS 2026HOPE: Hand-Object Pressure Estimation from Monocular VideosPaper Project Page
- CoRL 2024 WorkshopLearning to Transfer Human Hand Skills for Robot ManipulationsPaper Project Page
- ICRA 2009Graph-Based Robust Shape Matching for Robotic ApplicationPaper (PDF)
World Models & Video Generation
행동하기 전에 결과를 상상하는 모델Models that imagine the outcome before acting
무엇을 하나What we do
목표는 행동하기 전에 결과를 상상할 수 있는 로봇입니다. 비디오 생성 모델은 이미 세상이 어떻게 움직이는지 꽤 알고 있고, 이걸 로봇의 상상력으로 쓰는 것이 world model입니다. 저희는 세상의 모든 동적인 변화를 모델링하면서도 쉽게 제어할 수 있어서, 실제 physical AI로 바로 이어지는 생성 모델과 world model을 개발하는 것을 목표로 합니다.Our goal is a robot that can imagine the outcome before it acts. Video generation models already know a lot about how the world moves, and a world model turns that into imagination for robots. We aim to build generative models and world models that capture every dynamic change in the world, yet remain easy to control, so that they connect directly to physical AI.

논문Papers 4
- CoRL 2026Robot-Factored World Models via Robot RenderingPaper Project Page Code
- CVPR 2026Dexterous World ModelsPaper Project Page Code
- NeurIPS 2026SimuScene: Simulation-Ready Compositional 3D Scene Reconstruction from a Single ImagePaper Project Page Code
- ICLR 2026Target-Aware Video Diffusion ModelsPaper Project Page
Generative Human Modeling
사진 한 장에서 움직이는 3D 사람으로From one photo to a moving 3D human
무엇을 하나What we do
목표는 실제 사람과 똑같은 모습과 움직임을 가진 digital human입니다. 메타버스 아바타, AR/VR, 텔레프레즌스 같은 가상 환경에서 실제 사람처럼 보이고 실제 사람처럼 움직이며, 사용자가 얼굴, 머리, 의상을 자유롭게 바꿀 수 있는 극사실적 digital human을 만드는 것을 목표로 합니다. 이를 위해 사진 한 장이나 짧은 영상에서 움직이는 3D 사람을 복원하고, 몸, 옷, 머리카락을 나눠서 모델링해 각각 편집하고 조합할 수 있게 합니다.Our goal is a digital human that looks and moves exactly like a real person. In virtual environments such as metaverse avatars, AR/VR, and telepresence, it should appear and move like the real person, while letting users freely change the face, hair, and clothing. To get there, we reconstruct animatable 3D humans from a single photo or a short clip, and model body, clothing, and hair separately so that each can be edited and recombined.
논문Papers 13
- CVPR 2026 HighlightVanast: Virtual Try-On with Human Image Animation via Synthetic Triplet SupervisionPaper Project Page
- ICLR 2026Durian: Dual Reference Image-Guided Portrait Animation with Attribute TransferPaper Project Page
- ICCV 2025 OralHairCUP: Hair Compositional Universal Prior for 3D Gaussian AvatarsPaper Project Page
- CVPR 2025PERSE: Personalized 3D Generative Avatars from A Single PortraitPaper Project Page Code
- CVPR 2024GALA: Generating Animatable Layered Assets from a Single ScanPaper Project Page Code
- CVPR 2024PEGASUS: Personalized Generative 3D Avatars with Composable AttributesPaper Project Page Code
- ICCV 2023 OralChupa: Carving 3D Clothed Humans from Skinned Shape Priors using 2D Diffusion Probabilistic ModelsarXiv Project Page Code
- SIGGRAPH Asia 2025Audio Driven Real-Time Facial Animation for Social TelepresencePaper Project Page
- CVPR 2022 OralBANMo: Building Animatable 3D Neural Models from Many Casual VideosarXiv Project Page
- CVPR 2022Learning to Listen: Modeling Non-Deterministic Dyadic Facial MotionarXiv Project Page Code+Data
- CVPR 2021Body2Hands: Learning to Infer 3D Hands from Conversational Gesture Body DynamicsarXiv Project Page
- CVPR 2020 OralPIFuHD: Multi-Level Pixel-Aligned Implicit Function for High-Resolution 3D Human DigitizationarXiv Project Page Code Colab Demo
- NeurIPS 2020 Spotlight3D Multi-bodies: Fitting Sets of Plausible 3D Human Models to Ambiguous Image DataarXiv Project Page
Human Motion & Interaction Modeling
사람의 움직임, 그리고 물체·공간·타인과의 관계How people move, and how they relate to objects, spaces, and each other
무엇을 하나What we do
목표는 사람이 어떻게 움직이고, 물체를 어떻게 쓰고, 다른 사람과 어떻게 어울리는지를 3D로 이해하고 생성하는 것입니다. 몸, 손, 얼굴을 한 번에 복원하는 일에서 출발했고, 지금은 사람과 물체, 공간, 사람 사이의 상호작용으로 범위를 넓혔습니다. 이런 데이터는 모으기 어렵기 때문에 생성 모델에서 affordance 지식을 꺼내 쓰는 방법도 함께 연구합니다.Our goal is to understand and generate, in 3D, how people move, how they use objects, and how they interact with each other. We started by reconstructing body, hands, and face all at once, and have since extended this to interactions between people, objects, and spaces. Such data is hard to collect, so we also pull affordance knowledge out of generative models.
 Learning to Generate Human-Human-Object NeurIPS 2025
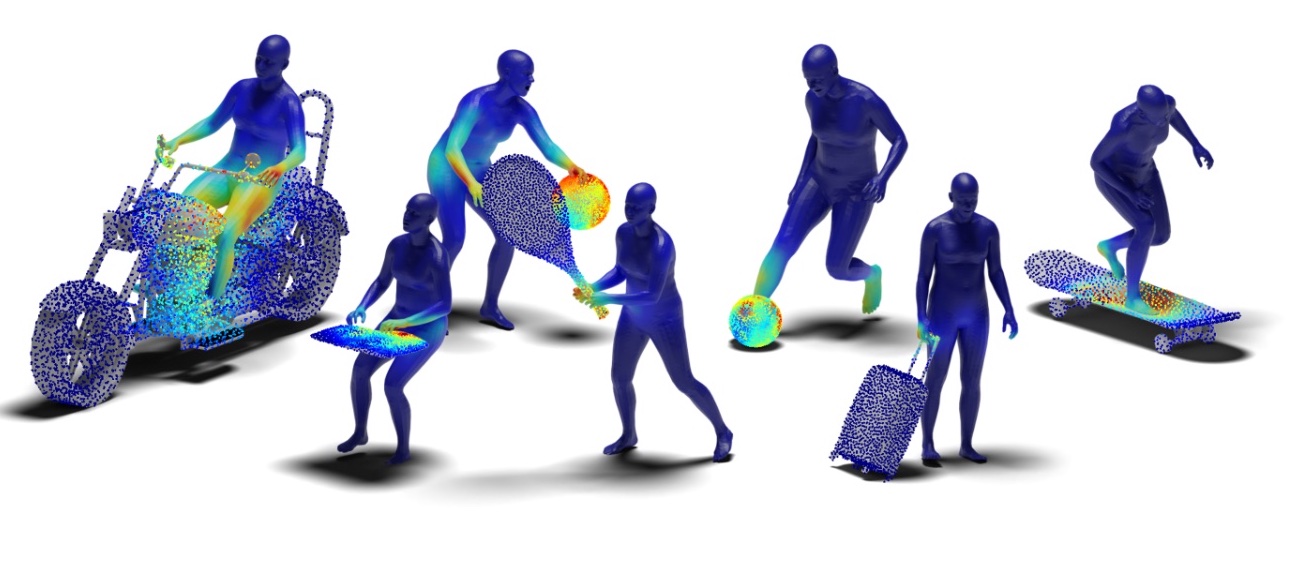 ComA ECCV 2024
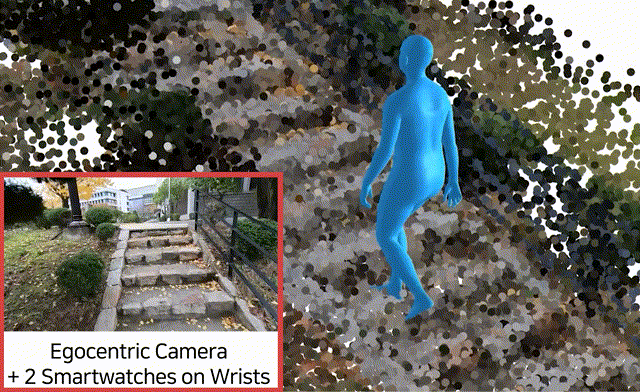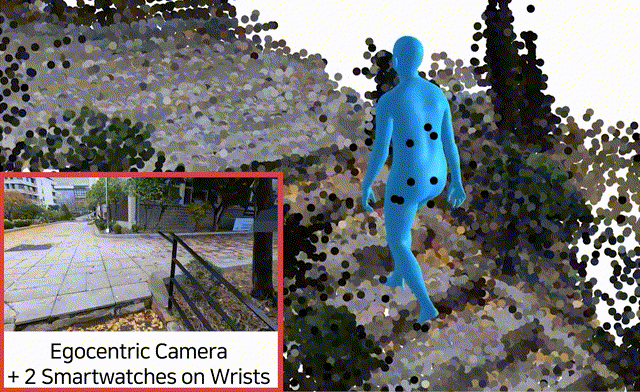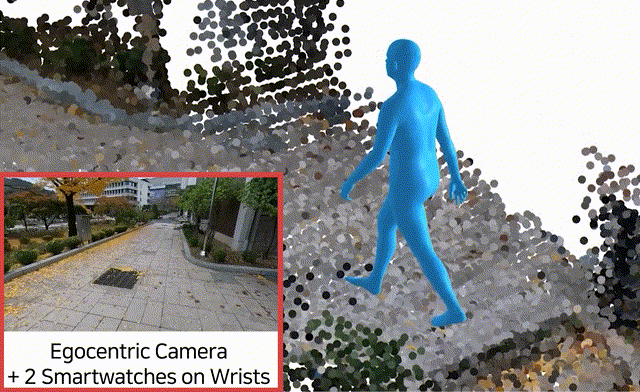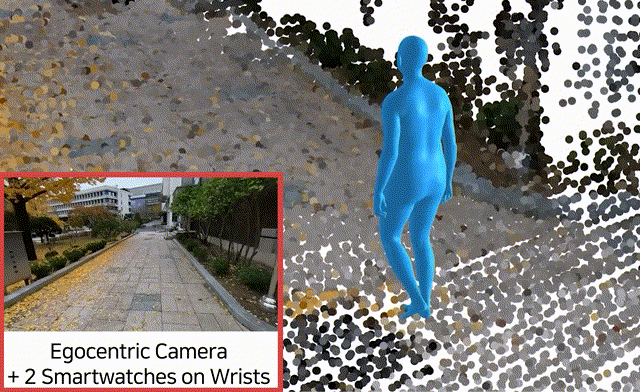 Mocap Everyone CVPR 2024
논문Papers 18
- NeurIPS 2026OmniEgoCap: Camera-Agnostic Sequence-Level Egocentric Motion ReconstructionPaper Project Page
- NeurIPS 2026HOPE: Hand-Object Pressure Estimation from Monocular VideosPaper Project Page
- NeurIPS 2025Learning to Generate Human-Human-Object Interactions from Textual DescriptionsPaper Project Page
- WACV 2026GraspDiffusion: Synthesizing Realistic Whole-body Hand-Object InteractionPaper Project Page
- ICCV 2025DAViD: Modeling Dynamic Affordance of 3D Objects using Pre-trained Video Diffusion ModelsPaper Project Page
- ICCV 2025Learning 3D Object Spatial Relationships from Pre-trained 2D Diffusion ModelsPaper Project Page
- ECCV 2024 OralBeyond the Contact: Discovering Comprehensive Affordance for 3D Objects from Pre-trained 2D Diffusion ModelsPaper Project Page
- CVPR 2024Mocap Everyone Everywhere: Lightweight Motion Capture With Smartwatches and a Head-Mounted CameraPaper Project Page Code
- CVPR 2024Guess The Unseen: Dynamic 3D Scene Reconstruction from Partial 2D GlimpsesPaper Project Page Code
- ICCV 2023 OralCHORUS: Learning Canonicalized 3D Human-Object Spatial Relations from Unbounded Synthesized ImagesPaper Project Page Code
- ICCV 2023NCHO: Unsupervised Learning for Neural 3D Composition of Humans and ObjectsarXiv Project Page Code
- ICCV 2023Locomotion-Action-Manipulation: Synthesizing Human-Scene Interactions in Complex 3D EnvironmentsarXiv Project Page Code
- CVPR 2020 OralYou2Me: Inferring Body Pose in Egocentric Video via First and Second Person InteractionsarXiv Project Page Code/Data
- ECCV 2020Perceiving 3D Human-Object Spatial Arrangements from a Single Image in the WildarXiv Project Page
- CVPR 2019 OralTowards Social Artificial Intelligence: Nonverbal Social Signal Prediction in A Triadic InteractionarXiv Code/Dataset Video
- CVPR 2019 OralMonocular Total Capture: Posing Face, Body and Hands in the WildarXiv Dataset and Code Video
- CVPR 2018 OralTotal Capture: A 3D Deformation Model for Tracking Faces, Hands, and BodiesPDF Supplementary Video Project Page
- ICCV 2019Single-Network Whole-Body Pose EstimationarXiv OpenPose Training OpenPose
Multi-Camera Capture Systems & Datasets
데이터가 없으면 데이터를 만든다If the data does not exist, we build it
무엇을 하나What we do
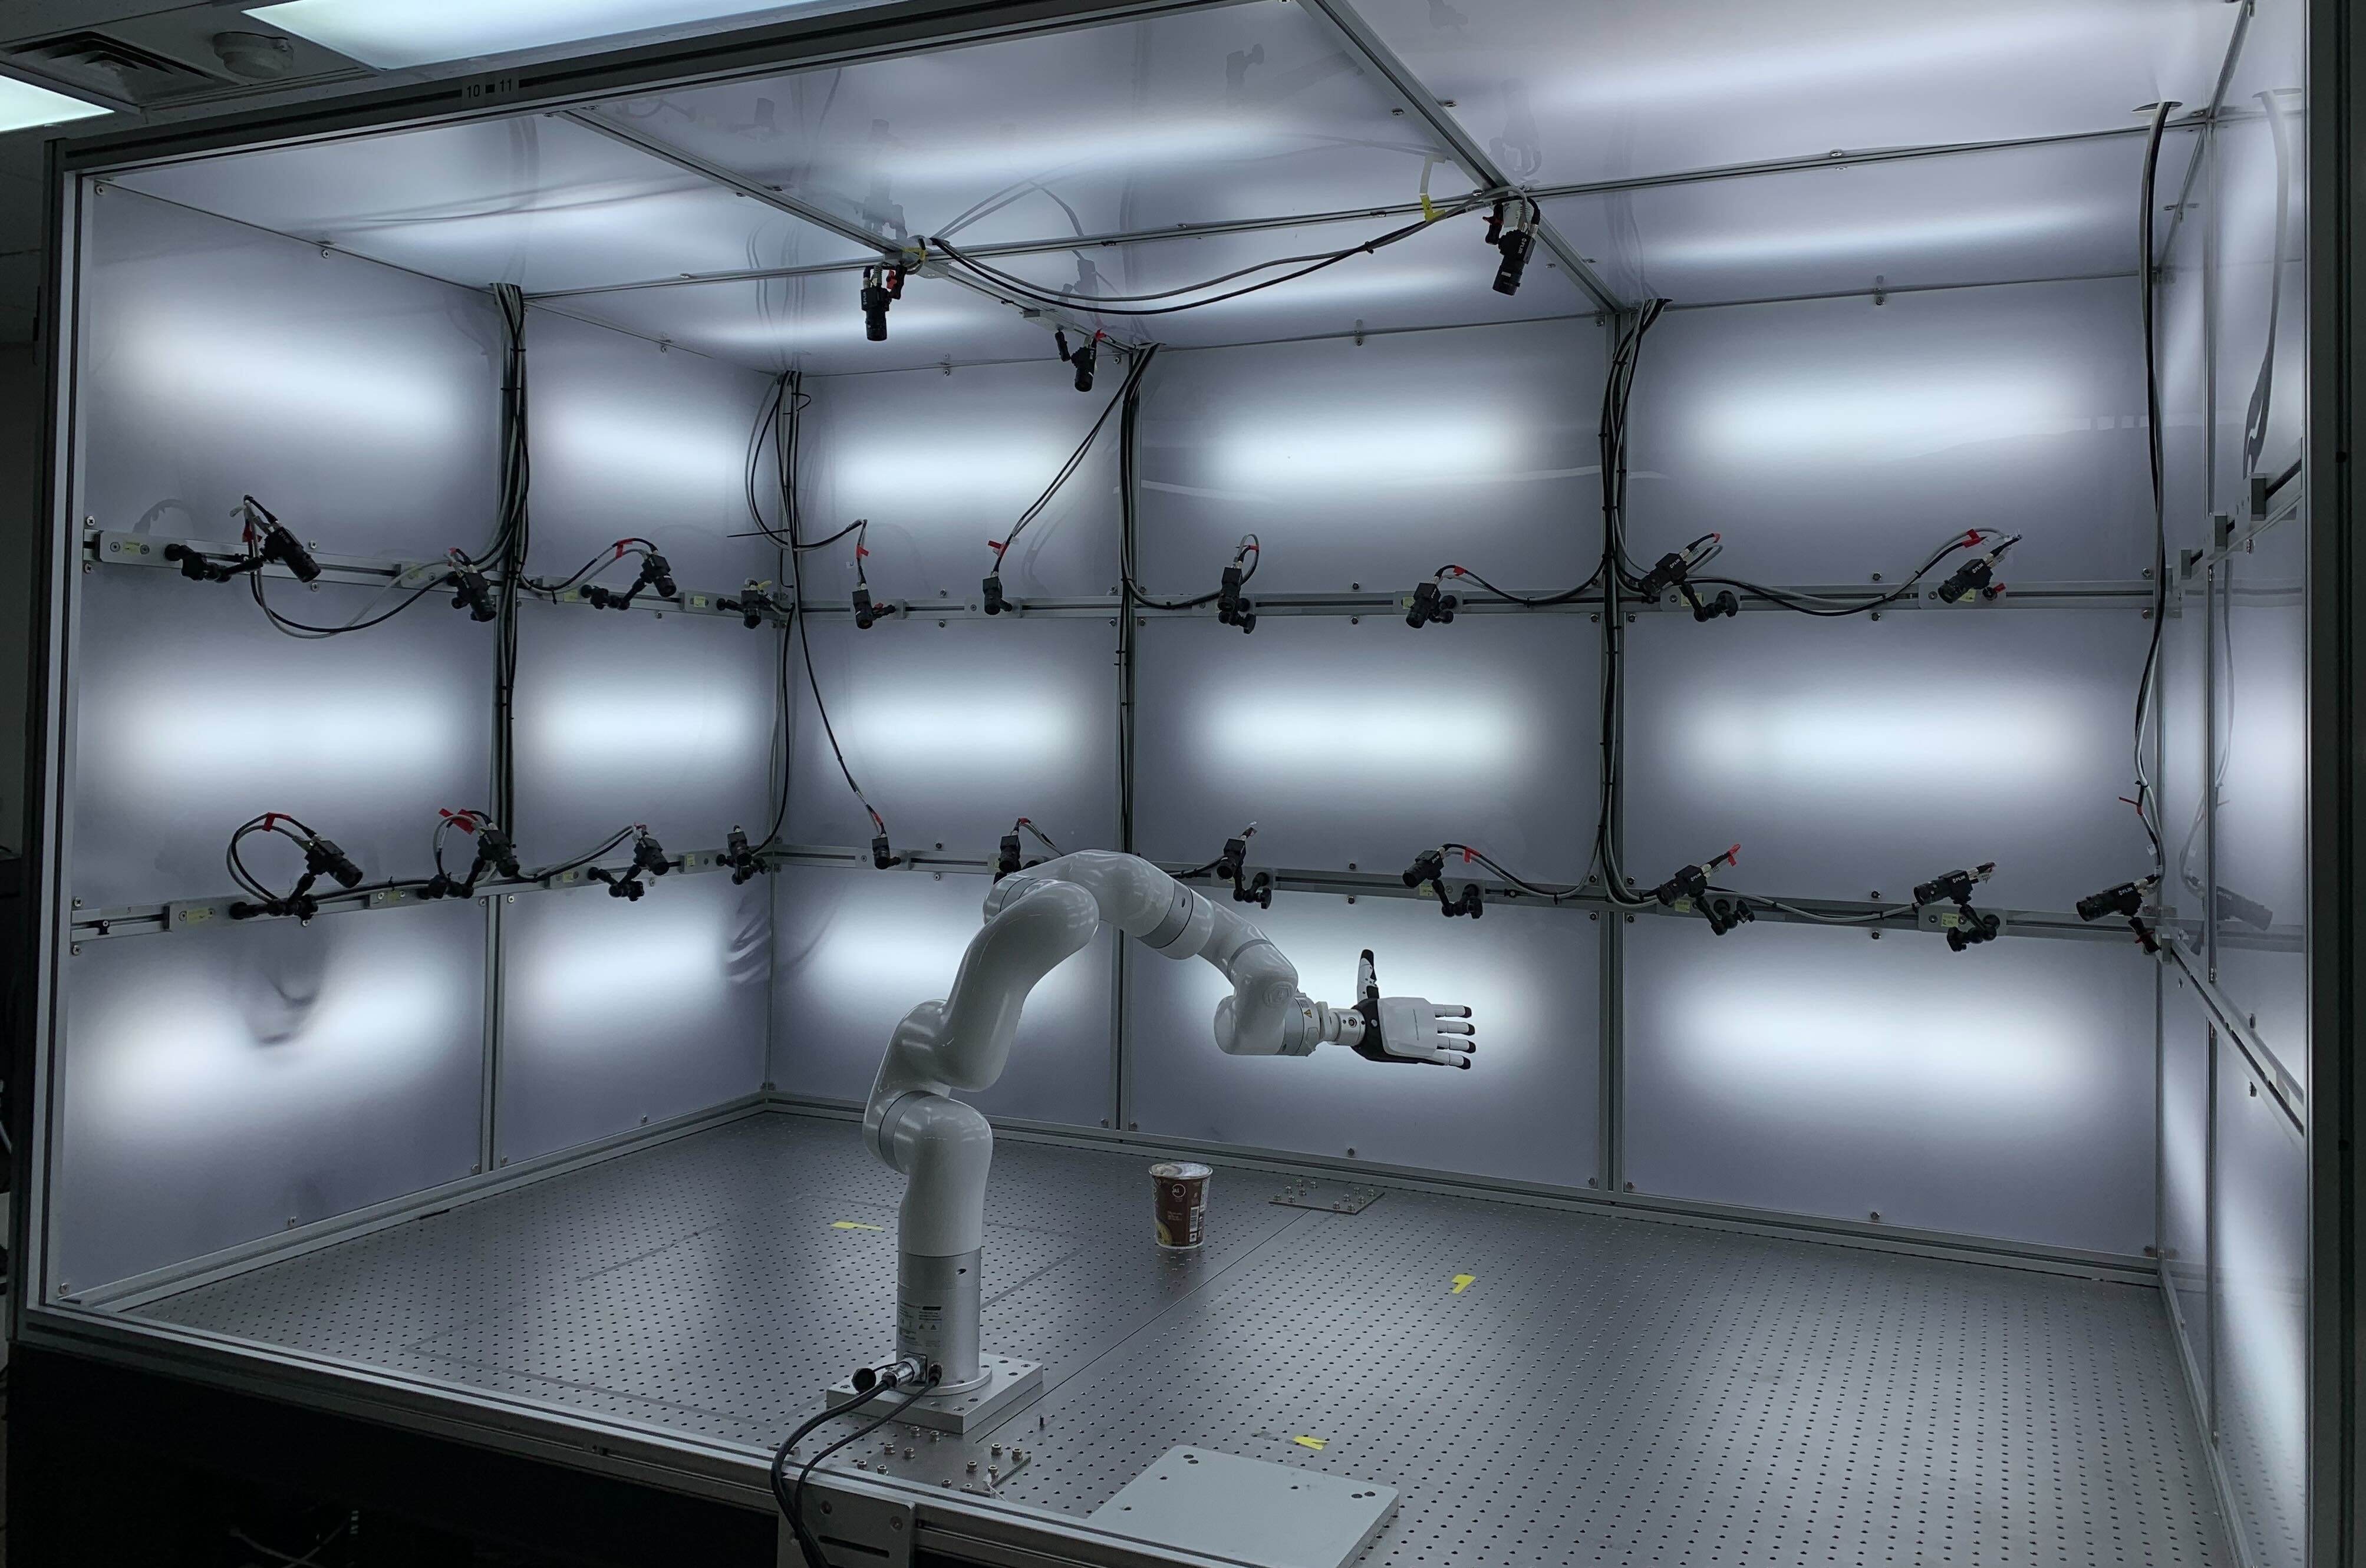
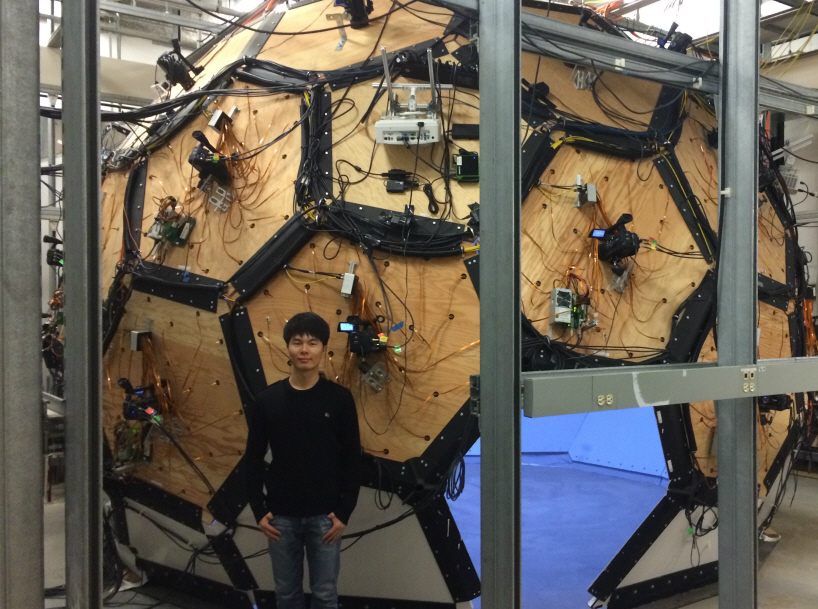
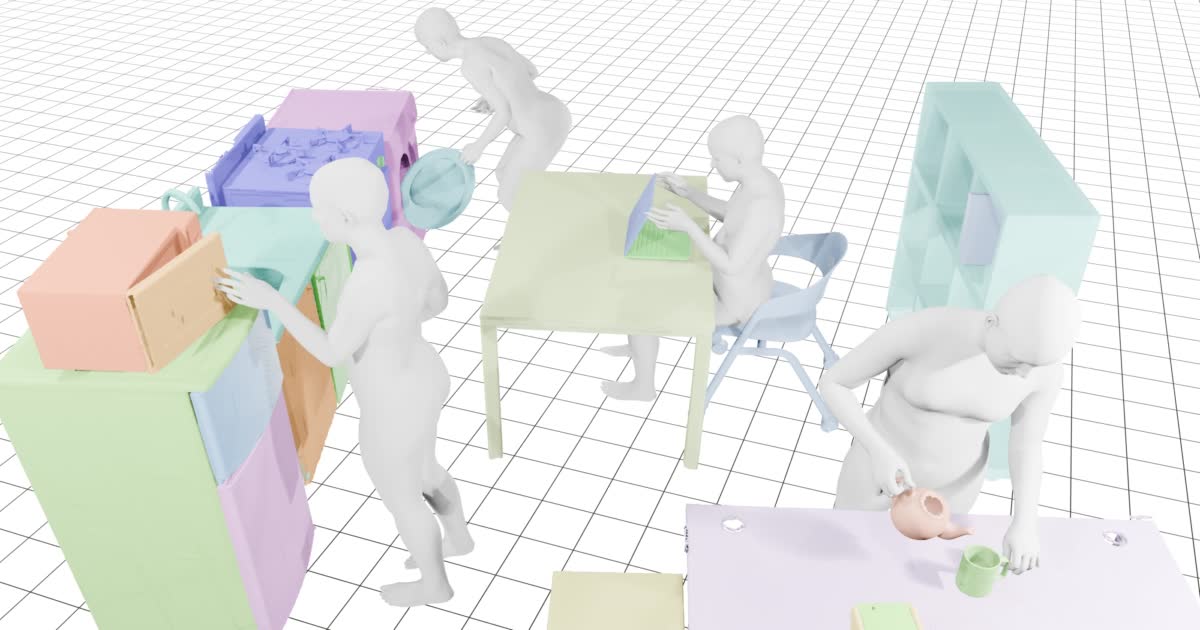
목표는 남이 갖지 못한 데이터를 직접 만드는 것입니다. 새 문제를 먼저 풀려면 측정 수단을 직접 가져야 합니다. 그래서 카메라 수십, 수백 대로 사람과 로봇을 동시에 찍는 시스템을 직접 짓고, 거기서 나온 데이터셋을 공개합니다. Panoptic Studio에서 OmniRobotHome까지, 다중 카메라 캡처는 저희 연구실이 오래 쌓아 온 강점이고, 이 분야에서 가장 앞선 시스템을 계속 만들어 가고 있습니다.Our goal is to build the data that no one else has. To solve a new problem first, you need your own measurement tools. So we build systems with tens to hundreds of cameras that observe people and robots at the same time, and we release the datasets that come out of them. From Panoptic Studio to OmniRobotHome, multi-camera capture has been one of our core strengths, and we keep building cutting-edge systems of this kind.

논문Papers 10
- Preprint 2026OmniRobotHome: A Multi-Camera Home Platform for Real-Time Human-Robot InteractionPaper Project Page
- Preprint 2026HRDexDB: A 4D Dexterous Grasping Dataset Across Human and Multiple Robot EmbodimentsPaper Project Page
- CoRL 2026AutoDex: An Automated Real-World System for Dexterous Grasping Data CollectionPaper Project Page Code
- CVPR 2025ParaHome: Parameterizing Everyday Home Activities Towards 3D Generative Modeling of Human-Object InteractionsPaper Project Page Code/Dataset
- CVPR 2022 OralEgo4D: Around the World in 3,000 Hours of Egocentric VideoarXiv Project Page
- CVPR 2017Hand Keypoint Detection in Single Images using Multiview BootstrappingarXiv Project Page Code Dataset
- TPAMI 2017Panoptic Studio: A Massively Multiview System for Social Interaction CapturePublished Version arXiv Dataset
- ICCV 2015 OralPanoptic Studio: A Massively Multiview System for Social Motion CapturePaper (PDF) Supplementary Project Page
- CVPR 2014 OralMAP Visibility Estimation for Large-Scale Dynamic 3D ReconstructionPaper (PDF) Project Page Dataset
- CVPR 2018Structure from Recurrent Motion: From Rigidity to RecurrencyPDF
Join Us
학부생 인턴 · 대학원Undergraduate Interns · Graduate Students
인턴, 석사, 박사 모두 모집 중입니다. 지원 방법과 자주 묻는 질문은 아래 문서에 정리해 두었습니다.We are recruiting interns, MS, and PhD students. How to apply and frequently asked questions are in the document below.
기업 협력Industry Collaboration
공동 연구, 산학 과제, 데이터 협력은 교수에게 직접 연락해 주세요.For joint research, sponsored projects, or data collaboration, please contact the professor directly.